Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
2 results
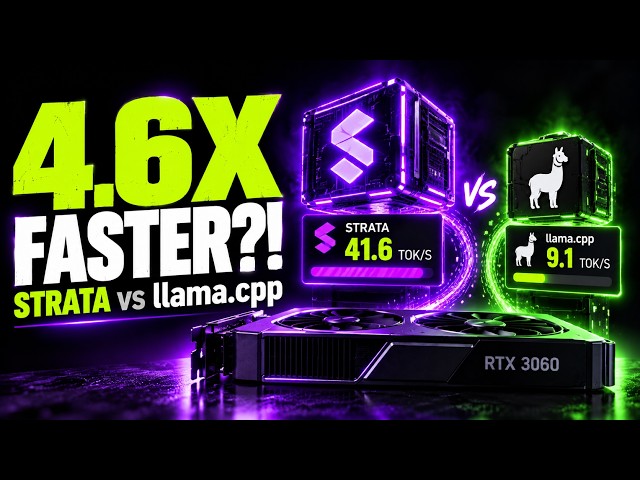
The same Qwen3.8-Flash-Next file on the same 12 GB RTX 3060: 9.1 tokens per second on llama.cpp, 41.6 on Strata. You asked ...
4,366 views
12h ago
The same Radeon GPU, the same Qwen model, no new quantization trick: 9.7 tokens per second became 37.2. llama.cpp already ...
17,026 views
5d ago