Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
737,948 results
520 subscribers
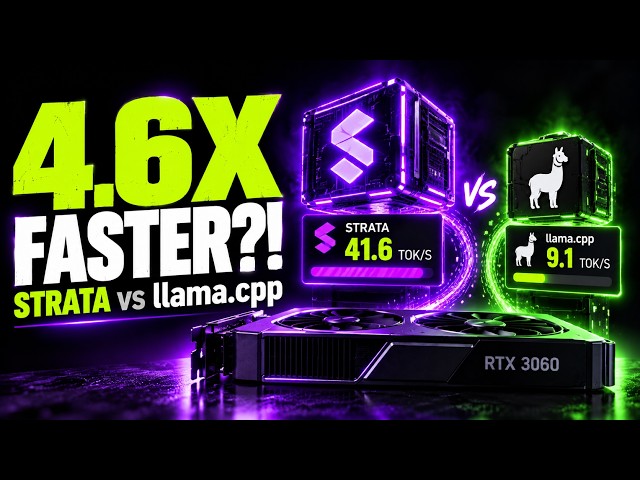
The same Qwen3.8-Flash-Next file on the same 12 GB RTX 3060: 9.1 tokens per second on llama.cpp, 41.6 on Strata. You asked ...
134 views
4h ago
The same Radeon GPU, the same Qwen model, no new quantization trick: 9.7 tokens per second became 37.2. llama.cpp already ...
16,907 views
5d ago
Four M5 Ultra Mac Studios, wired together with Thunderbolt 5 cables, ran Meta's 816-billion-parameter Muse Spark Open locally ...
632 views
7d ago
A jailbroken PlayStation 5 is now running Qwen 3.8 27B locally on its own GPU, at around 20 tokens per second. Not through the ...
2,180 views
10d ago
Microsoft just ran a 137-billion-parameter coding model locally on a Windows laptop. Not through an API, not on a remote server, ...
385 views
13d ago
llama.cpp just made the exact same model run more than twice as fast on the exact same GPU. It is not a new quantization format, ...
11,158 views
2w ago
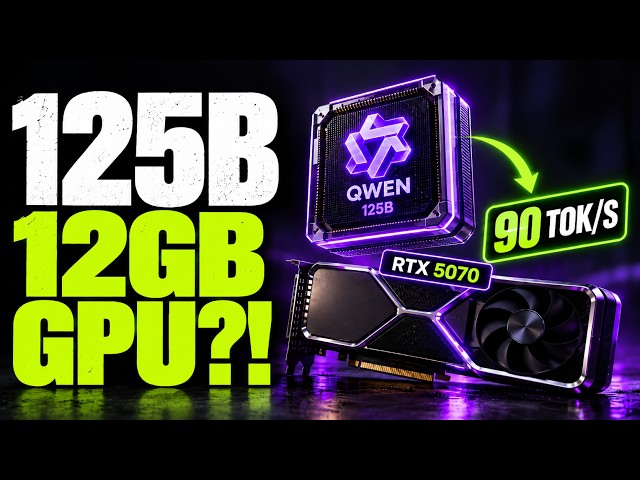
A 125-billion-parameter AI model, generating almost 100 tokens per second. On an RTX 5070 with 12 GB of VRAM. Not a server ...
1,404 views
850 tokens per second. From a 35-billion-parameter model. On one RTX 5090, with the full 262K-token context window. That is ...
113 views
3w ago
A 502 GB model file. One RTX 5090 with 32 GB of VRAM. About 128 GB of system memory. Even combined, the model doesn't fit ...
960 views
A 27-billion-parameter Qwen model ran with a one-million-token agent workspace on a laptop with a 24 GB GPU — and still ...
4,351 views
1.38K subscribers
7 subscribers
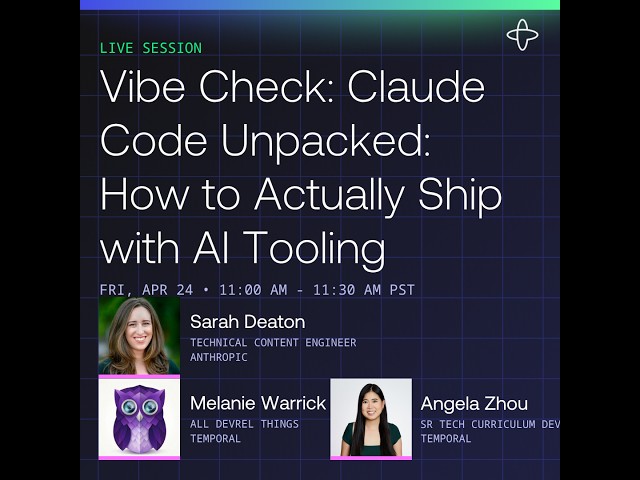
Sarah Deaton, Technical Content Engineer at Anthropic and the person who owns the Claude Code docs, joined myself and my ...
414 views
Streamed 6mo ago
Watch the all-new Galaxy Z Fold series, our most powerful and versatile foldables yet. Designed to move naturally with your life ...
19,285,132 views
Streamed 3mo ago
Shulamit Cohen lived a life few could imagine: a housewife raising children in Beirut while secretly passing critical intelligence to ...
249,838 views
8mo ago
8 subscribers
Jewish tradition treats Hebrew as far more than a language. Its letters are said to have existed before creation, forming the ...
11,472 views
2mo ago
Get the latest updates from Anthropic's engineering and product leaders at the Code with Claude 2026 opening keynote in San ...
258,599 views
Streamed 5mo ago
Not clickbait, the full claude code source code got leaked… Thank you Greptile for sponsoring! Check them out at: ...
199,319 views
6mo ago
Kimi API (Extra 15% bonus for new users' first purchase, until Nov 30) ...
18,462 views
2d ago
An 82GB-class AI model is generating text directly on an Android phone with only 12GB of RAM. No cloud server. No external ...
6,878 views
1mo ago
Get the latest updates from Anthropic's engineering and product leaders at the Code with Claude 2026 opening keynote in ...
79,694 views
5mo ago
Code review is the new bottleneck. Codex brings pull requests, review feedback, and private conversations about your code into ...
92,036 views
Disfruta el #GalaxyUnpacked este 25 de febrero de 2026. #GalaxyAI Conoce por qué ahora todo es más fácil.
19,082 views
Streamed 8mo ago